
Probado experienced a major incident on March 23, 2021 affecting VoIP (Voice over IP) and Data Services (Hosting), lasting 19h 14m. The incident has been resolved; the full update timeline is below.
Affected components
Update timeline
- identified Mar 23, 2021, 02:18 PM UTC
We're aware of issues some users are encountering in regarding connectivity to Data Services. This is in relation to an update carried out early AM by one of the core datacentres down in London. We have failed over to alternative routes while changes are being reverted and we are monitoring the situation. Please note: This is a wide spread issue not isolated to your services. Updates to Follow.
- identified Mar 23, 2021, 02:19 PM UTC
Status: Awaiting Update from Partners - Next Update @ 15:00
- monitoring Mar 23, 2021, 03:02 PM UTC
The Failover to alternative connection routes appears to of alleviated the connectivity issues for all services. We will continue to liaise with our Datacentre Partners and monitor connectivity between peering locations .
- resolved Mar 24, 2021, 09:32 AM UTC
The Peering issue with the LINX Network has been resolved and traffic has returned to normal.
- postmortem Mar 24, 2021, 09:37 AM UTC
At approximately 1:30pm we received notice that users were encountering difficulty in connecting to datacentre services. Upon investigation we found that communication between our datacentre and LINX \(London Internet Exchnage\) peering service \(one of the key network exchanges in the UK\) was lost. Linx Peering screenshot shown below 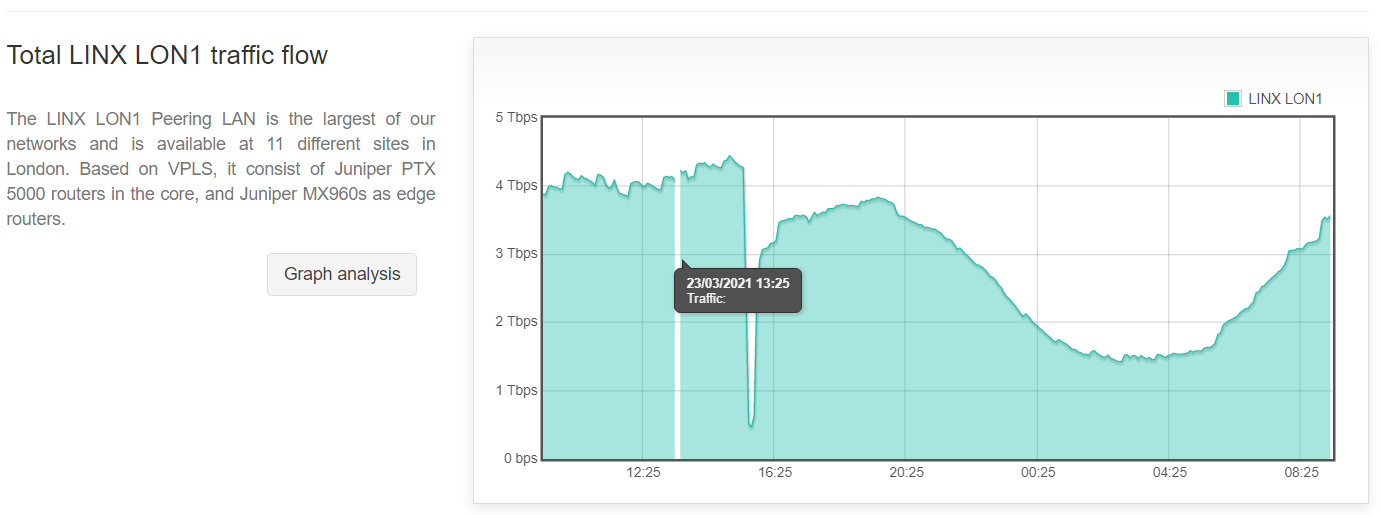 \(Source: [Stats Overview page | LINX Portal](https://portal.linx.net) \) Upon the datacentre finding this issue, they immediately failed over to alternative routes to re-establish connections and out datacentre connectivity was restored for all users and services. We then continued to monitor throughout the day. There was a second drop in this service but as failovers were already in place our client base remained unaffacted. We’re awaiting a Root Cause Analysis from Linx for the reason for this outage.